 Paul Scott
The statistical tests dissertation researchers select should match their research question, outcome variable, predictor and study design. The main decision is whether you’re comparing groups, examining an association or predicting an outcome.
Your choice also depends on whether observations are independent or related, and whether the data meet the test’s assumptions. Start with the question and design, then select the procedure.
Key Takeaways
- Identify your research question, dependent variable, independent variable and measurement levels before selecting a test.
- Use t-tests or ANOVA for group comparisons, correlation for relationships, chi-square for categorical associations and regression for prediction or adjustment.
- Justify assumptions and sample size, then report effect sizes and uncertainty alongside p-values.
Choose a Statistical Test in the Right Order
A defensible statistical analysis starts before you open SPSS, R or another statistics package.
Identify the Question and Variables
Work through these decisions in order:
- State your research question. Decide whether you need a description, comparison, association or prediction.
- Identify the dependent variable. This is the outcome you’re explaining or comparing.
- Identify the independent variable. This is the grouping variable, exposure or predictor relevant to your question.
- Establish measurement levels. Use descriptive statistics to inspect your data and distinguish continuous measurements, ordered categories and unordered categories.
A correlation question may involve two variables without designating either as dependent. However, regression requires you to identify an outcome.
Our guide to writing a focused dissertation question helps you define measurable variables before choosing an analysis.
Establish Whether Observations Are Independent or Related
Separate participants in unrelated groups usually provide independent observations. Measurements taken before and after an intervention in the same participants are related.
Matched pairs also create dependence. Students within the same class or patients within one clinic may share characteristics. This clustering can require multilevel models or other methods that account for dependence.
Treating repeated measurements as separate participants can underestimate uncertainty.
Quick Reference for Common Dissertation Tests
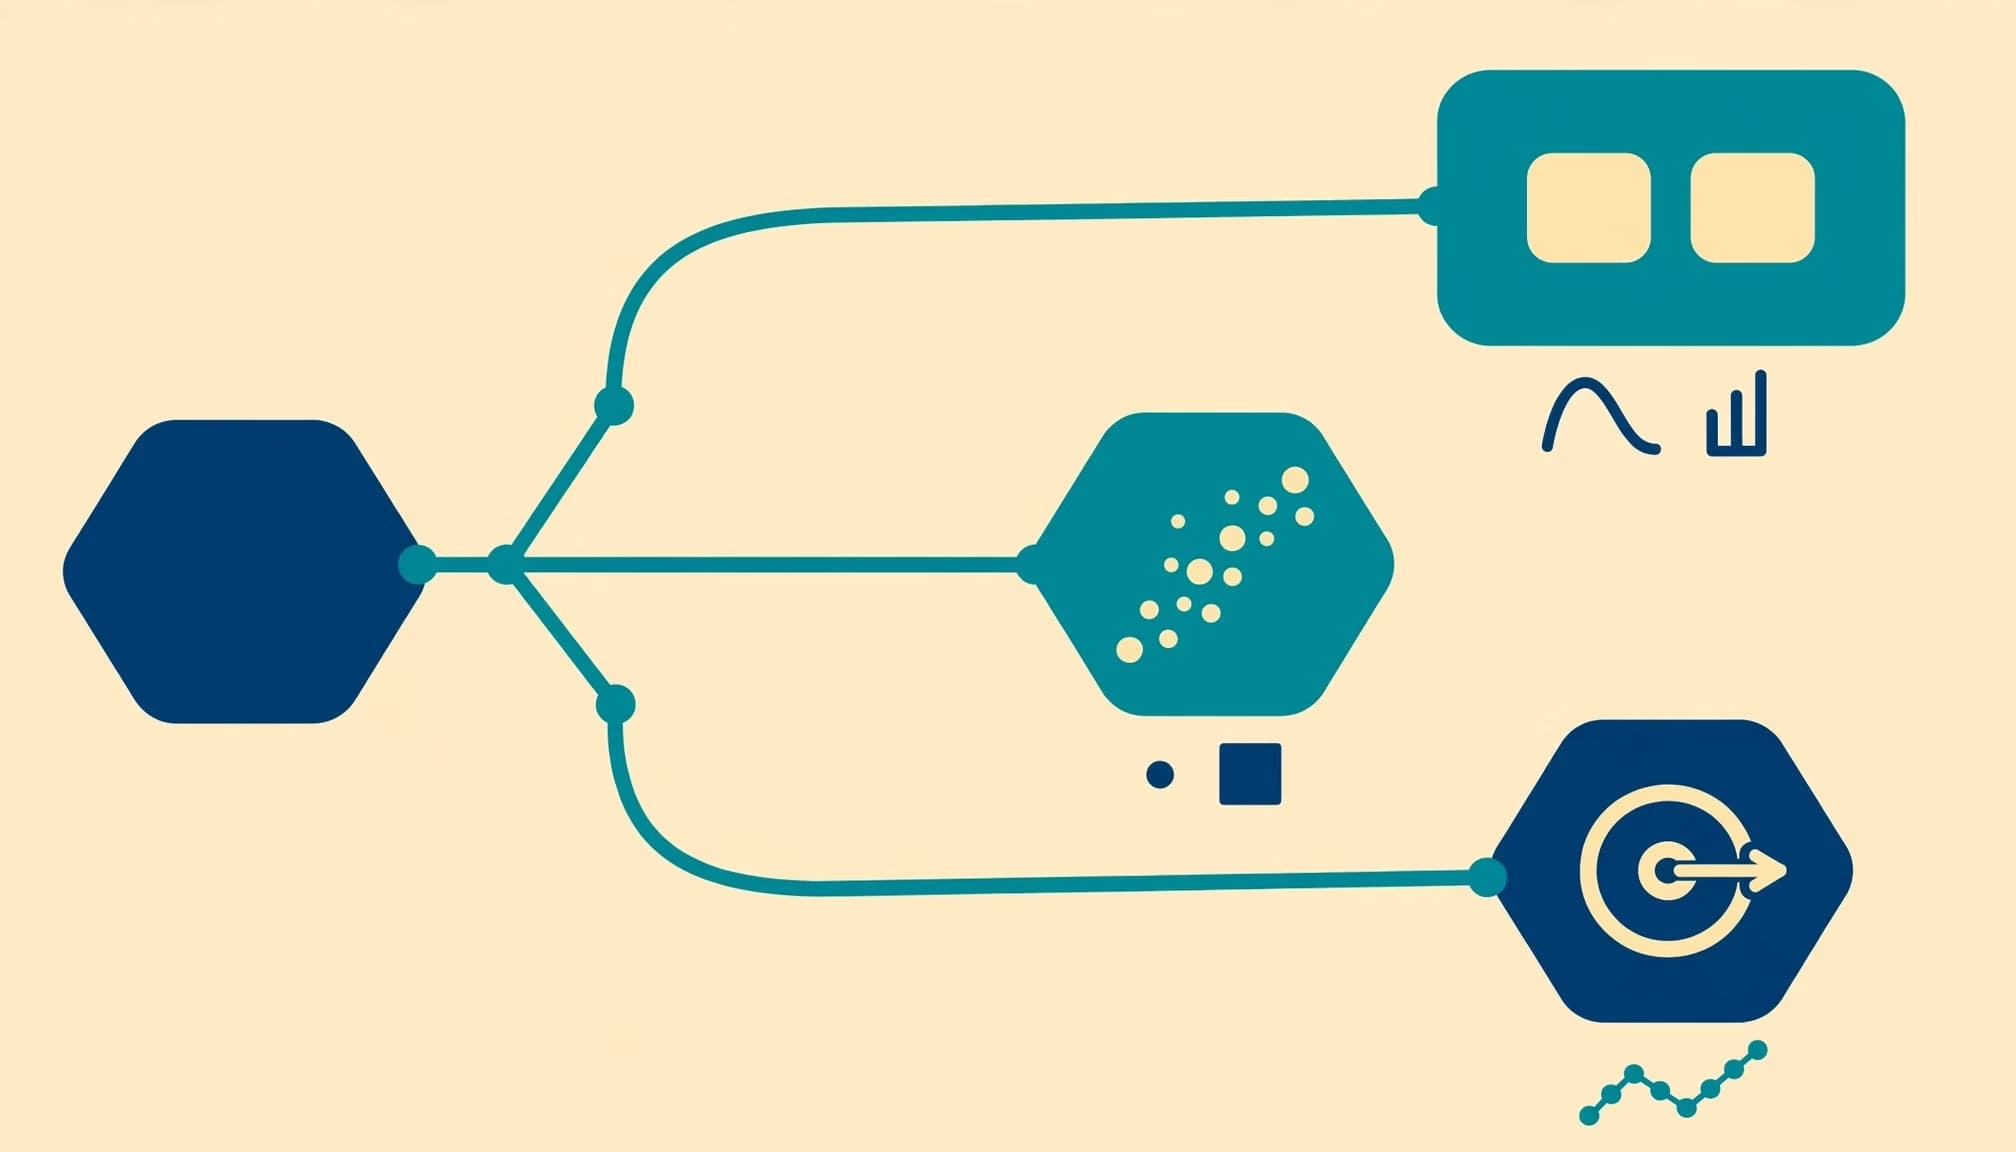
This table identifies starting points; assumptions and study design determine the final choice.
| Research Goal | Starting Test |
|---|---|
| Compare two independent groups on a continuous outcome | Independent samples t-test |
| Compare two related continuous measurements | Paired samples t-test |
| Compare three or more independent groups | One-way ANOVA |
| Compare three or more measurements per participant | Repeated measures ANOVA |
| Examine linear association between continuous variables | Pearson correlation |
| Examine monotonic association using ranks | Spearman correlation |
| Examine association between categorical variables | Chi-square test of independence |
| Compare one categorical variable with expected proportions | Chi-square goodness-of-fit |
| Predict an outcome or adjust for other variables | Regression matched to outcome type |
The UCLA statistical test-selection guide provides a broader reference across common software packages. Descriptive questions may need descriptive statistics, estimates and confidence intervals rather than a hypothesis test.
Compare Groups With t-Tests and ANOVA
For group comparisons, first count the groups or occasions. Then establish whether the observations are related.
Independent and Paired t-Tests
An independent samples t-test compares two separate groups on one continuous outcome. Its question concerns a difference between group means.
A paired-samples t-test compares two related measurements, usually from the same participants. It analyses within-person differences.
Check independence, serious outliers and the relevant normality assumption. For the paired test, normality concerns difference scores, not each occasion separately. The conventional pooled independent test also assumes homogeneity of variance, or equal group variances. Welch’s t-test accommodates unequal variances.
One-Way and Repeated-Measures ANOVA
One-way ANOVA compares mean outcomes across three or more independent groups. Repeated-measures ANOVA compares three or more measurements from the same participants.
Check residual distributions, outliers and the appropriate variance assumptions. Repeated-measures ANOVA also requires attention to sphericity; a Greenhouse-Geisser correction can address violations.
A significant ANOVA establishes that at least one mean differs. It doesn’t identify which groups differ. Tukey’s HSD is a common post hoc test after a conventional one-way ANOVA when its assumptions fit.
Nonparametric Alternatives
The usual alternatives are the Mann-Whitney U test, also called the Wilcoxon rank-sum test, for independent groups; the Wilcoxon signed-rank test for paired measurements; the Kruskal-Wallis test for independent groups; and Friedman for repeated measurements.
These rank-based procedures answer different questions from mean-based tests. Mann-Whitney U, for instance, isn’t automatically a test of median differences; that interpretation needs comparable distribution shapes.
Measure Associations With Correlation and Chi-Square
Association questions concern how variables vary together. The measurement level determines which approach fits.
Pearson and Spearman Correlation
Pearson correlation measures linear association between two continuous variables. Its coefficient ranges from -1 to 1: the sign indicates direction, whilst the magnitude describes strength. Unlike rank-based association, Pearson correlation measures linear rather than monotonic relationships.
Inspect a scatterplot for linearity and influential outliers. Distributional assumptions also matter for conventional significance tests and confidence intervals.
Spearman rank correlation measures monotonic association using ranks. It suits ordinal variables, including individual Likert-type items, and can suit non-normal data. However, it doesn’t solve every distributional problem or capture every curved relationship.
Neither coefficient establishes causation.
Chi-Square Tests for Categorical Variables
A chi-square test of independence examines association between two categorical variables. In contrast, goodness-of-fit compares the observed frequencies of one categorical variable with expected frequencies.
Both require counts rather than percentages entered as observations. Each observation should contribute appropriately without unaccounted dependence.
Small expected cell frequencies can make the chi-square approximation unreliable. Fisher’s exact test is a common option for sparse two-by-two tables. Combine categories only when the grouping has substantive meaning, rather than to obtain significance.
Match Regression to Your Outcome
Regression analysis estimates relationships whilst accounting for other measured variables. Select the model according to the outcome, rather than the predictor’s measurement level.
Linear regression predicts a continuous outcome. Binary logistic regression models a two-category outcome through its probability or odds. Multinomial logistic regression handles unordered categories, whilst ordinal logistic regression handles ordered categories.
Each model has additional assumptions. Ordinal logistic regression, for example, commonly requires the proportional-odds assumption.
Choose potential confounders using subject knowledge and your research question. In retrospective research, available records also restrict what you can measure and adjust for. Selecting predictors solely because their individual p-values are small can produce a poorly justified model.
Adjustment doesn’t remove unmeasured confounding or turn observational associations into causal effects. Our comparison of observational and experimental study designs explains that distinction.
Check Assumptions and Statistical Power
A familiar test name doesn’t make an analysis appropriate. Your dataset must support the procedure and the interpretation.
Diagnose the Relevant Assumptions
Check independence through the design, not a normality test. Then examine distributions, group variances, linearity and serious outliers where relevant.
Normality requirements usually concern model residuals, within-group errors or paired differences. They don’t mean every variable must follow a normal distribution. Similarly, a non-normal predictor doesn’t automatically rule out linear regression.
Use relevant plots and model output in SPSS alongside diagnostic tests. Investigate unusual values before deleting them, and document any exclusions. Nonparametric tests still require suitable observations, measurement levels and sample sizes.
Plan Sample Size Around Your Analysis
Before collecting data, base sample size on the planned analysis, a meaningful effect, anticipated variability, significance threshold and desired power. Account for missing responses, attrition and the sampling design.
The university-developed G*Power analysis tool supports power calculations for many common tests. Record your inputs and their justification rather than copying another dissertation’s participant count.
For existing datasets, explain the limits on precision and sensitivity. Our guide to dissertation sampling methods separates analytical requirements from recruitment quality.
A larger convenience sample can improve precision without removing selection bias.
Justify Your Test and Report the Result
Explain in your methodology why the test answers your question and fits your dissertation data analysis. Name the outcome and predictor, measurement levels, independent or related design, assumptions and planned response to violations.
Our dissertation methodology examples show how analytical choices connect to the wider research design.
The consequences of weak justification are visible in a Cairo dissertation audit covering 62 MD dissertations. The authors reported appropriate methods in 13 studies, with an appropriateness rate of 24.5%, and misinterpretation in 82.3% of results. Among ten dissertations with non-significant primary outcomes, median power was 35.5%, ranging from 6% to 60%. These findings describe that audit, not dissertations generally.
For your statistical analysis, report the analysed sample size, suitable descriptive statistics, estimates, confidence intervals and relevant test information. Include the test statistic, degrees of freedom where applicable, p-value and an appropriate effect size. For Pearson correlation, report the coefficient and a suitable confidence interval. Explain missing data because different analyses may include different participants.
The ASA statement on p-values explains why significance doesn’t measure effect size or practical importance.
A significant result in one group and a non-significant result in another don’t establish that the groups differ. Test the between-group contrast or interaction directly.
Frequently Asked Questions About Dissertation Statistical Tests
When Should I Use a Nonparametric Test?
Consider one when the research question concerns ranks or ordinal measurements, or when a suitable parametric analysis isn’t supported. Don’t switch automatically because one normality test returns a small p-value. Examine the design, distribution and quantity you want to estimate.
For two independent groups, use the Mann-Whitney U test. The Kruskal-Wallis test compares three or more independent groups, while the Wilcoxon signed-rank test is suitable for paired measurements.
Can I Use Pearson Correlation for Likert Responses?
An individual Likert item is ordinal, so Spearman is often appropriate. A justified summed multi-item scale may support Pearson, depending on its measurement properties and analysis assumptions. Explain your reasoning; supervisor approval alone isn’t a statistical justification.
Does a Non-Significant Result Prove No Relationship?
No. It means the analysis didn’t provide sufficient evidence against its null hypothesis at the chosen threshold. Examine the estimate and confidence interval. A wide interval may remain compatible with meaningful effects.
Choose a Test You Can Defend
The right statistical test follows your question, variables and study design. Assumptions and sample adequacy then determine whether that choice remains defensible.
Write down that reasoning before running the analysis. Finally, base your conclusions on the estimated effect and its uncertainty, not on a statistical significance label alone.